# Benchmarks
> Published Elide benchmarks: hello-world startup for JavaScript and Python, and HTTP serving throughput and latency, against Node, Bun, Deno and CPython, with machine, date, command and recording.
Benchmarks published for Elide 1.6.0. Each number links to a terminal recording or downloadable raw measurement reports.
JavaScript startup and HTTP serving were re-recorded on October 15 with the release build
`1.6.0`, without the optional Python component. Python results retain their October 2 recording.
No JVM benchmark is published.
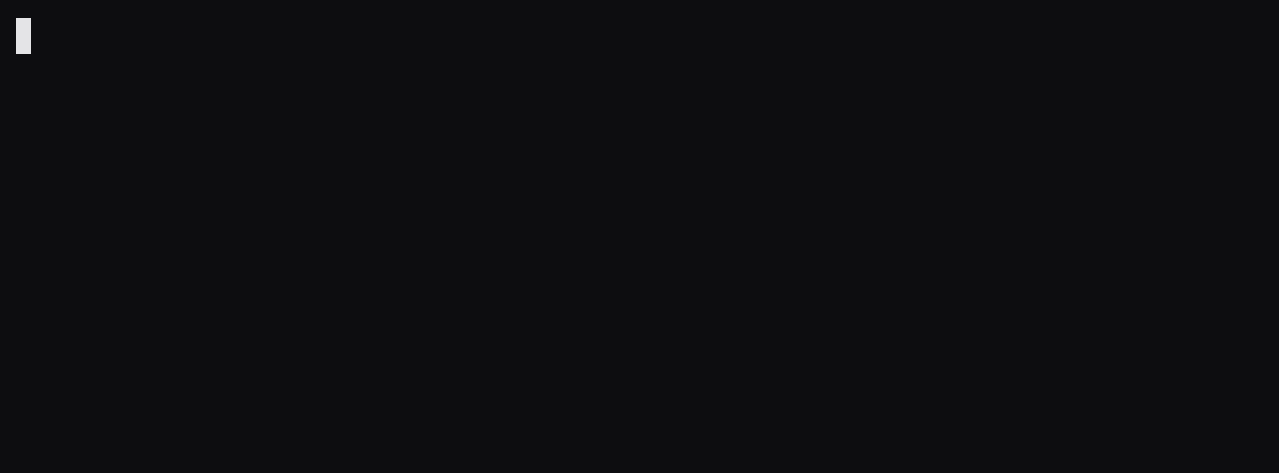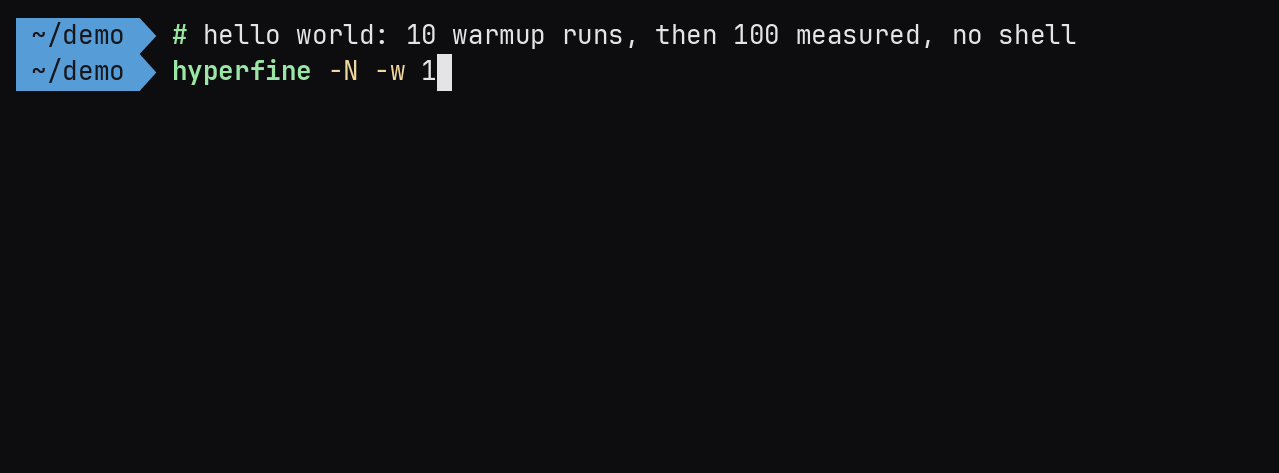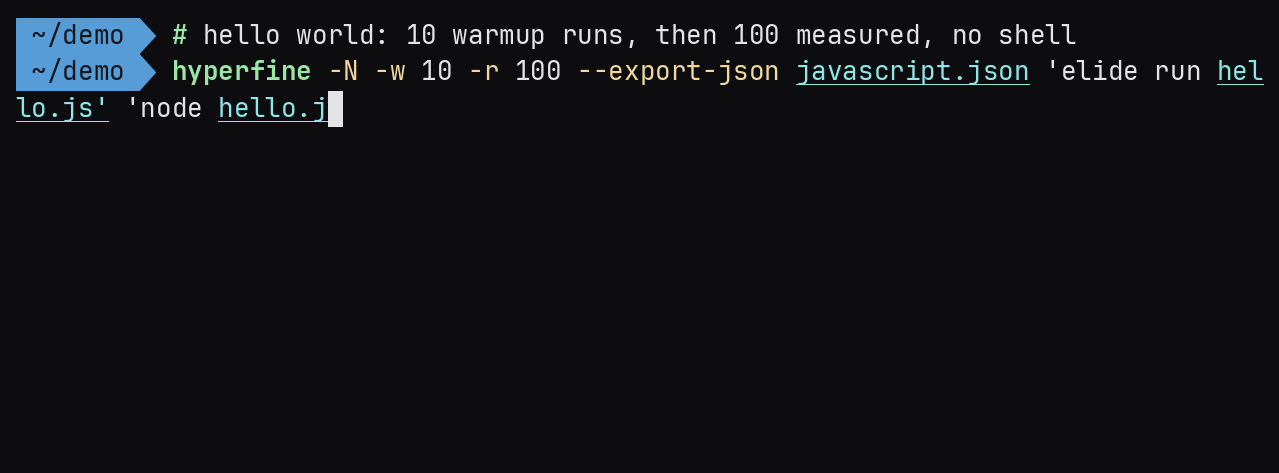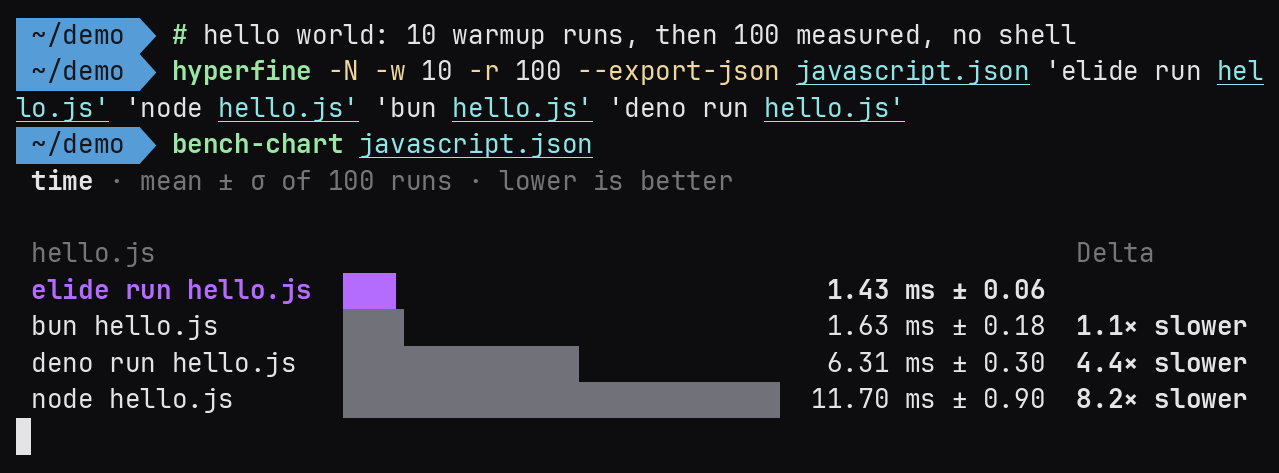
1. JavaScript hello-world startup, mean: Elide 1.43 ms, Bun 1.63 ms, Deno 6.31 ms, Node 11.70 ms.
2. Python hello-world startup, mean: Elide 4.8 ms, CPython 6.0 ms.
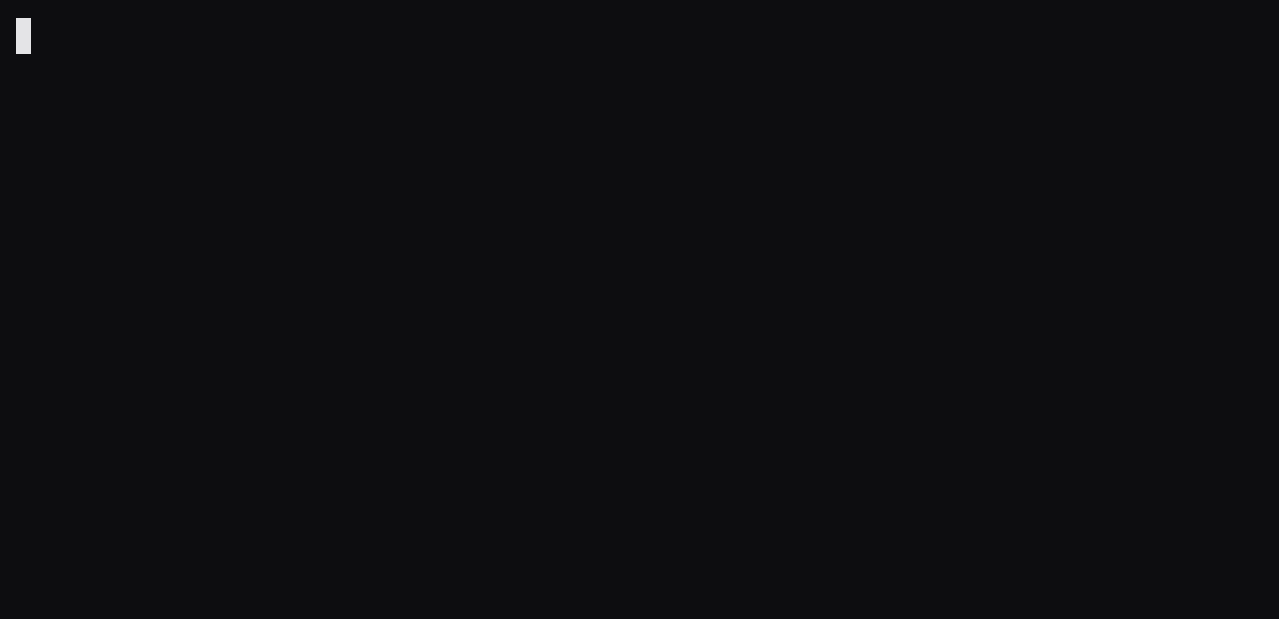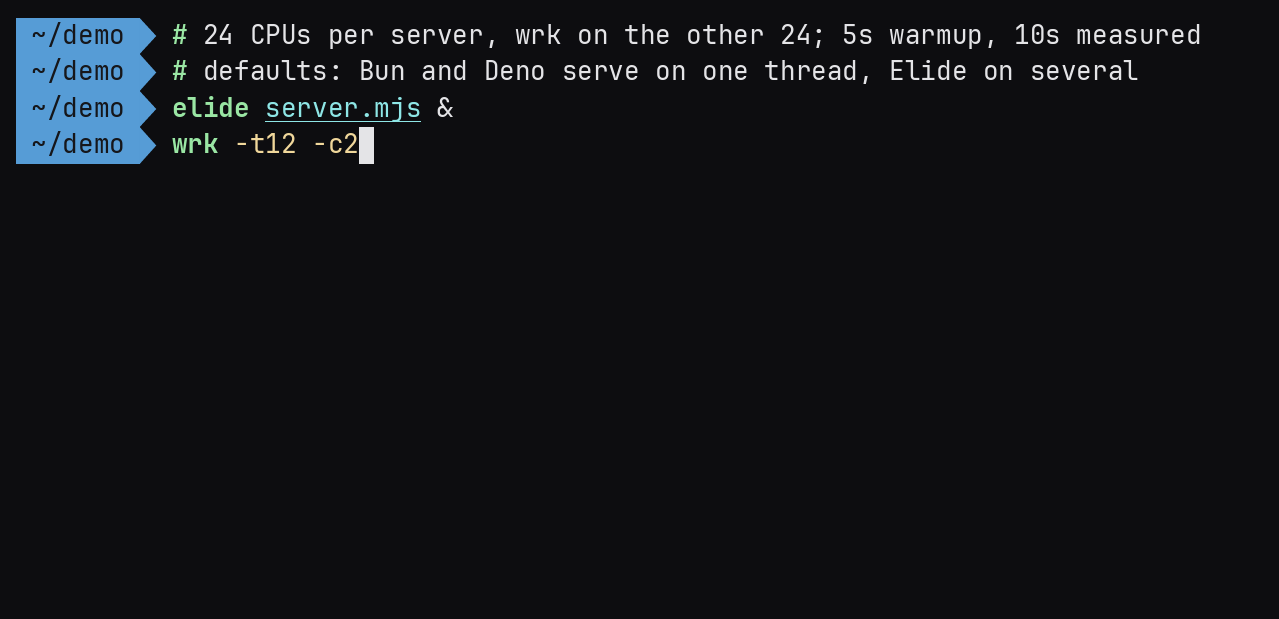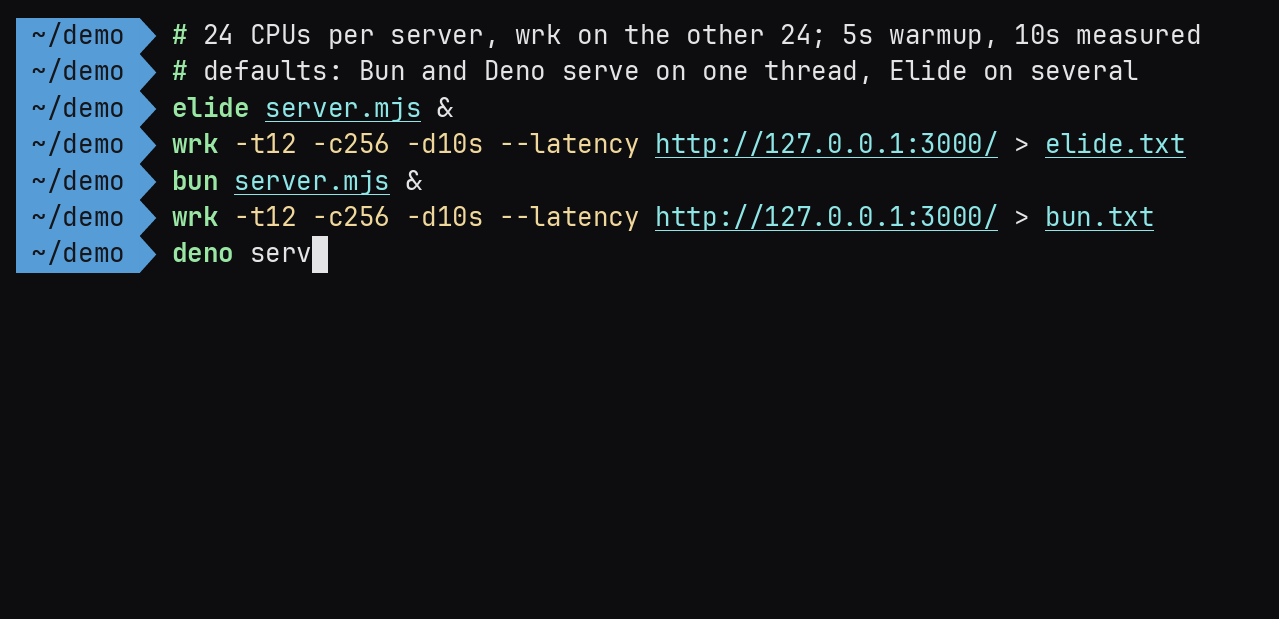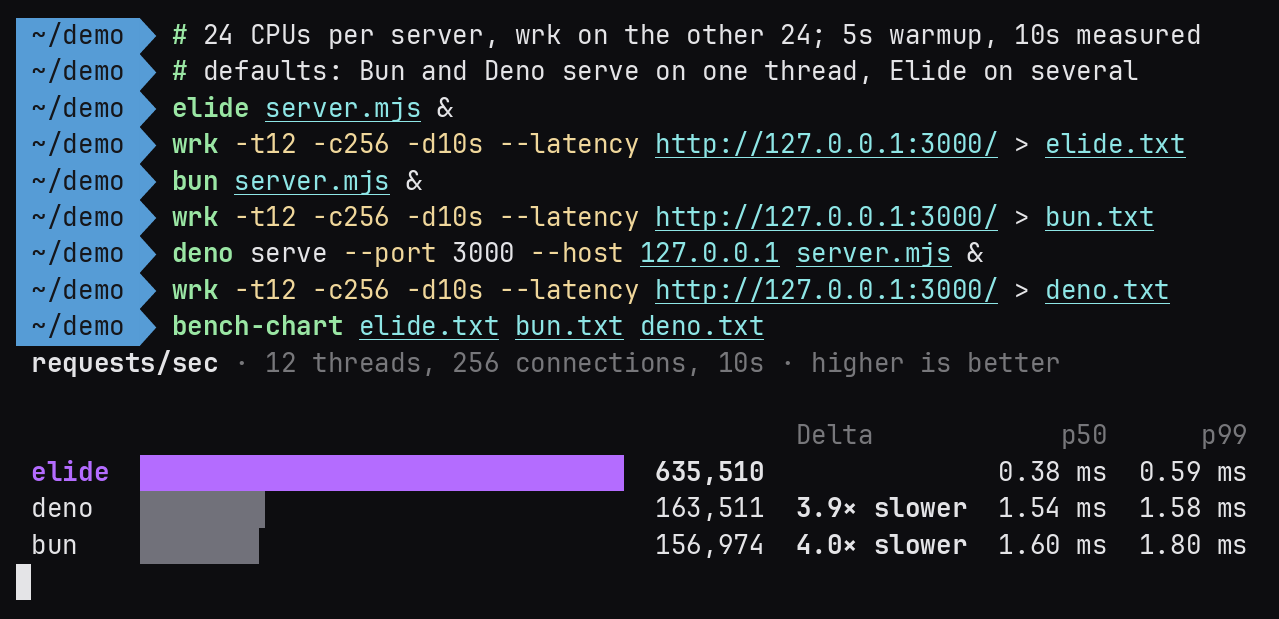
3. HTTP serving, requests per second: Elide 635,510, Deno 163,511, Bun 156,974, Node 123,519.
## JavaScript startup
Time to run a one-line `hello.js` (`console.log("Hello, World!");`) and exit. Lower is better.
| Runtime | Version | Command | Mean |
| --- | --- | --- | --- |
| Elide | 1.6.0 | `elide run hello.js` | 1.43 ± 0.06 ms |
| Bun | 1.4.2 | `bun hello.js` | 1.63 ± 0.18 ms |
| Deno | 2.9.7 | `deno run hello.js` | 6.31 ± 0.30 ms |
| Node | 24.21.0 | `node hello.js` | 11.70 ± 0.90 ms |
| Detail | Value |
| --- | --- |
| Tool | `hyperfine -N -w 10 -r 100`: no shell, 10 warmup runs, 100 measured |
| Machine | 24-core AMD Ryzen Threadripper PRO 9965WX Linux workstation |
| Date | 2026-10-15 |
| Recording | `bench-startup` (below) |
 ## Python startup
Time to run a one-line `hello.py` (`print("Hello, World!")`) and exit. Lower is better.
| Runtime | Version | Command | Mean |
| --- | --- | --- | --- |
| Elide | 1.6.0 | `elide run hello.py` | 4.8 ± 0.3 ms |
| CPython | not recorded | `python3 hello.py` | 6.0 ± 0.3 ms |
| Detail | Value |
| --- | --- |
| Tool | `hyperfine -N -w 10`: no shell, 10 warmup runs |
| Machine | 24-core Linux workstation |
| Date | 2026-10-02 |
| Recording | `bench-startup-python` (not published as a clip) |
Python needs the optional component (`elide setup python`); see [Python with Elide](https://elide.help/docs/python).
## HTTP serving
Requests per second and latency for a fetch handler that returns `Hello, World!`. Higher requests per second and lower
latency are better.
```javascript
// server.mjs
export default {
port: 3000,
hostname: "127.0.0.1",
fetch() {
return new Response("Hello, World!");
},
};
```
| Runtime | Version | Command | Requests/s | p50 latency | p99 latency |
| --- | --- | --- | --- | --- | --- |
| Elide | 1.6.0 | `elide server.mjs` | 635,510 | 0.38 ms | 0.59 ms |
| Deno | 2.9.7 | `deno serve --port 3000 --host 127.0.0.1 server.mjs` | 163,511 | 1.54 ms | 1.58 ms |
| Bun | 1.4.2 | `bun server.mjs` | 156,974 | 1.60 ms | 1.80 ms |
| Node | 24.22.0 LTS | `node node-default.mjs` | 123,519 | 2.03 ms | 2.24 ms |
| Detail | Value |
| --- | --- |
| Tool | `wrk -t12 -c256 -d10s --latency`, after a discarded 5-second warmup run |
| Machine | 24-core AMD Ryzen Threadripper PRO 9965WX Linux workstation; server on 24 logical CPUs, `wrk` on 24 others |
| Date | 2026-10-15 |
| Recording | `bench-serve` (below) |
The server CPU mask was `0-11,24-35`; the client mask was `12-23,36-47`: twelve physical cores and their SMT
siblings per side, in a private network namespace. The table shows one recorded run on this machine.
Each server used its defaults and one JavaScript application context. Elide also uses transport threads.
This is an apples-to-apples comparison of default settings with the same handler and load, not a comparison of
maximum multi-core capacity. Node uses an equivalent native `http` handler with the same 13-byte body;
HTTP headers remain runtime-specific. Its separate run used the same machine, CPU masks, private network
namespace, warmup, and load settings, with no reported socket or HTTP status errors.
[Node’s raw report](https://elide.help/assets/benchmarks/results/default/node/run-1/measured.txt) and handler are included
in the [reproduction package](https://elide.help/assets/benchmarks/http-serving-1.6.0.zip). The recording below covers the original three runtimes.
 ## Multi-context peak serving
The same Elide binary reached **10,697,938 requests/s** with 24 application contexts in one process and
HTTP/1.1 pipeline depth 16. Three fresh-server runs measured **10,697,938, 10,376,454, 10,648,229 requests/s**;
the mean was **10,574,207 requests/s**. Every warmup and measured run reported zero request errors.
Ordered-response preflight checked status, framing, and body bytes before each load.
This is a separate tuned throughput experiment. It does not establish a speedup over the default-serving
comparison above, an off-host capacity estimate, or a maximum for other runtimes. Pipeline latency measures
batches; we do not publish it as individual-request latency.
| Configuration | Default-serving comparison | Peak multi-context serving |
| --- | --- | --- |
| Elide throughput | 635,510 requests/s | 10,697,938 requests/s peak |
| JavaScript execution | One context per runtime | 24 contexts in one Elide process |
| HTTP load | No pipelining | Pipeline depth 16; 4096 varied URLs |
| Load generator | 12 threads; 256 connections | 16 threads; 256 connections |
| Warmup / measurement | 5 seconds / 10 seconds | 60 seconds / 60 seconds; three fresh servers |
| Handler | Constant 13-byte Hello, World! response | URL parsing; nine-byte hello-GET response |
| CPU budget | 12 physical server cores + SMT; 12 for client | 12 physical server cores + SMT; 12 for client |
| Scheduling | Default serving settings | Explicit inline serving; io_uring |
| Network | Private namespace, loopback | Host loopback |
| Build | Elide 1.6.0, without Python | Same Elide binary; Serial GC |
### Parallel runtime comparison
We also ran Bun 1.4.3, Deno 2.9.7, and Node.js 24.22.0 LTS against the peak workload above:
same server/client CPU masks, 256 connections, sixteen client threads, pipeline depth 16,
URL parsing, and nine-byte response. Each configuration had three fresh-server runs, each with
60 seconds warmup and 60 seconds measurement. Runtimes ran sequentially, with configurations
interleaved between repeats. These results do not use estimated process scaling or memory penalties.
| Runtime | Configuration | Peak requests/s | Measured-run errors |
| --- | --- | ---: | --- |
| Elide 1.6.0 | 24 contexts; published runs | 10,697,938 | 0 |
| Deno 2.9.7 | 24 worker isolates; `--parallel` | 4,152,202 | 0 |
| Bun 1.4.3 | 24 processes; `reusePort` | 3,573,293 | 0 |
| Node.js 24.22.0 LTS | 24 `node:cluster` workers | 2,801,194 | 0 |
| Node.js 24.22.0 LTS | One process; reference | 217,282 | 139 timeouts across 3 runs |
A fresh Elide control run reached **11,416,311 requests/s** without errors. The comparison retains
the previously published three-run peak instead of replacing it with this single control.
The competitor measurements were:
| Configuration | Run 1 | Run 2 | Run 3 |
| --- | ---: | ---: | ---: |
| Bun, 24 processes | 3,571,718 | 3,573,293 | 3,560,084 |
| Deno, 24 workers | 4,123,713 | 4,039,565 | 4,152,202 |
| Node.js, 24 workers | 2,791,261 | 2,798,668 | 2,801,194 |
| Node.js, one process | 180,500 | 217,282 | 168,524 |
Node’s single-process measured runs reported 48, 42, and 49 timeout events respectively; their
warmups reported 62, 52, and 64. All other measured runs and warmups reported zero connection,
read, write, response-status, and timeout errors. Counts are wrk events, not failed-request rates.
Bun uses Linux port sharing; Deno uses worker isolates within one process; Node uses its built-in
cluster coordinator. No external proxy is involved. Node uses its native `http` API; the other
handlers use fetch-style APIs. All parse the URL and construct the response, but default HTTP
headers differ. This is a comparison of these configurations, not a ceiling for any runtime.
RSS savings were not benchmarked.
[Download sources and raw results](https://elide.help/assets/benchmarks/http-serving-1.6.0.zip) ·
[Comparison summary](https://elide.help/assets/benchmarks/results/comparison/summary.json)
## How contexts share a process
```sh
elide run --contexts=auto server.mjs
```
This enables automatic context sizing; `--contexts=24` requests a fixed count. The entry module runs in each
context. Contexts handle requests concurrently, keep JavaScript globals and module state separate, and share
one managed heap and garbage collector. Eligible parsed and JIT-compiled code can be reused across contexts.
Sharing does not make ordinary JavaScript objects globally accessible. GC pauses and a process failure can
affect all contexts; use external coordination for application data that must be shared.
### Architecture comparison
This compares independent-process scaling with Elide's multi-context model; other runtimes can also offer
worker-thread models. Shared infrastructure can reduce duplication, but application work and context-local
state still scale with the workload.
| Resource | Multiple processes | Elide contexts |
| --- | --- | --- |
| Replicas | One process each | One context each |
| Managed heap | Separate | ✅ Shared |
| GC pauses | ✅ Per process | ⚠ May span contexts |
| Parsed / JIT code | Per process | ✅ Shareable code reused |
| Runtime setup | Per process | ✅ Once per process |
| Telemetry pipeline | Per process | ✅ Shared batching/export |
| Request spans | Per request | Per request |
| Process metrics | One stream per process | ✅ One process stream |
| Listener | Port sharing / routing | ✅ One shared listener |
| I/O resources | Per process | Shared topology; per-owner queues |
| JS globals | ✅ Isolated | ✅ Isolated |
| App client pools | Per replica | Per context unless shared by an API |
| Coordination | IPC / external storage | Explicit APIs / external storage |
| CPU scheduling | Process / worker threads | Context owner threads |
| Crash isolation | ✅ Per process | ⚠ Shared process |
| Lifecycle | Manage each process | ✅ One lifecycle |
Telemetry infrastructure is amortized across contexts; per-request instrumentation still costs work.
Telemetry export was disabled for these measurements. Neither telemetry savings nor memory savings were
measured by the HTTP benchmark.
The peak benchmark also explicitly selects inline scheduling and io_uring, uses unlimited memlock, and
pipelines requests. The simple command above does not enable all those benchmark settings. The download
contains the exact command and environment; [performance tuning](https://elide.help/docs/performance#multi-context-serving)
explains the application-facing context setting. This diagram describes architecture, not measured memory savings.
## Benchmark environment
These details apply to the October 15 JavaScript startup and HTTP measurements. The older Python recording
has only the machine information listed in its own section; do not infer the same kernel or distro for it.
| Detail | Value |
| --- | --- |
| CPU | AMD Ryzen Threadripper PRO 9965WX; 24 physical cores, 48 hardware threads, one socket |
| Memory | 128 GB installed; approximately 122.9 GiB visible to Linux |
| OS | Ubuntu 26.04.1 LTS, x86-64 |
| Kernel | Linux `7.0.0-34-generic` |
| CPU policy | Performance governor; frequency boost enabled |
| Server / client placement | Twelve physical cores plus SMT siblings per side; disjoint CPU masks |
| Client | wrk 4.1.0; exact options in the comparison table and download |
| Elide | `1.6.0`, release, without optional Python; Serial GC |
| Binary SHA-256 | `545a4d99db099cf91a35bad8b33bb7e8d1a37a7361c6ba2b62c6e94691fff5c6` |
| Peak results | [Raw reports and environment](https://elide.help/assets/benchmarks/http-serving-1.6.0.zip) |
Default server CPUs: `0-11,24-35`; client: `12-23,36-47`.
Peak server CPUs: `0-2,6-8,12-14,18-20,24-26,30-32,36-38,42-44`;
client: `3-5,9-11,15-17,21-23,27-29,33-35,39-41,45-47`.
The differing masks preserve the same physical-core budget; they are recorded, not assumed interchangeable.
## Run them yourself
[Download the rerunnable benchmark package](https://elide.help/assets/benchmarks/http-serving-1.6.0.zip)
([SHA-256](https://elide.help/assets/benchmarks/http-serving-1.6.0.zip.sha256)). It includes a Makefile,
a dependency-free Python runner, JavaScript fixtures, the pipelined wrk client, raw results, and instructions.
Bring Linux, Python 3, Make, util-linux, wrk, and your runtime binaries. No runtime binaries are bundled; use
the recorded version and checksum for an exact binary match, or record your own version when comparing.
```sh
make run ARGS="--mode peak --binary /path/to/elide --contexts 24 --server-cpus YOUR_SERVER_CPUS --client-cpus YOUR_CLIENT_CPUS --out results"
```
Choose CPU masks for your machine. The download documents locked-memory limits, namespace differences,
and commands for the default Elide, Bun and Deno comparison. Results vary with hardware and configuration.
The same files and commands work on any machine; expect different absolute numbers. [Performance
Tuning](https://elide.help/docs/performance#measure-startup) covers the setup: real binaries rather than version-manager shims, pinning the
server and `wrk` to separate cores, and a warmup run before measuring.
## See also
- [Performance tuning](https://elide.help/docs/performance) for the settings that change speed and memory
- Comparisons per runtime: [Node](https://elide.help/docs/elide-for-node#benchmarks), [Bun](https://elide.help/docs/elide-for-bun#benchmarks),
[Deno](https://elide.help/docs/elide-for-deno#benchmarks), [Python](https://elide.help/docs/elide-for-python#benchmarks)